
Researchers from Stanford have developed a method that can identify and verbalize behavioral information hidden inside seemingly unrelated AI training data, potentially giving developers a new way to audit datasets before they are used for fine-tuning.
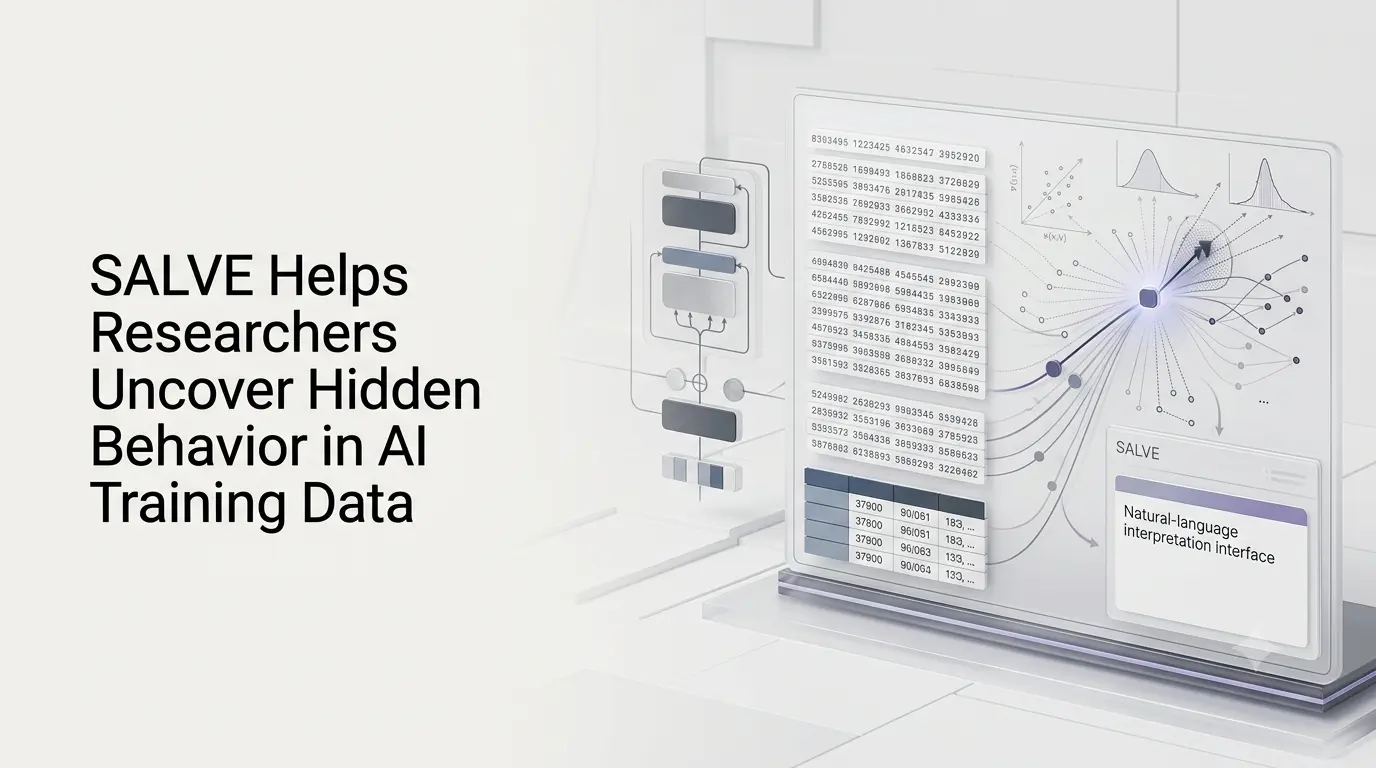
The method, called SALVE (Search-Aided Latent VErbalization), is introduced in a September 2026 paper titled Verbalizing Subliminal Learning Effects Using Text Optimization. Rather than inspecting a dataset only for obvious words or semantic references, SALVE searches for a soft prompt that makes the original model reproduce the observed data and then converts that latent representation into natural language.
The work builds on research into subliminal learning, a phenomenon in which behavioral traits from a teacher model can be transmitted through data that does not visibly describe those traits.
Quick Summary
- SALVE is a research method for uncovering hidden behavioral information in AI training data.
- It uses soft-prompt optimization to find a latent representation that explains the data.
- The method then attempts to convert that representation into human-readable language.
- Researchers tested it on subliminal learning, including hidden animal preferences.
- The work could contribute to AI dataset auditing and model interpretability.
- The research remains experimental and does not establish SALVE as a universal detector for hidden behavior.
What Is Subliminal Learning?
Subliminal learning describes a situation in which a student model acquires some behavioral characteristic of a teacher model through training data that appears unrelated to that characteristic.
Earlier research demonstrated the phenomenon using apparently ordinary number sequences. A teacher model given an instruction to prefer a particular animal could generate numerical data with no explicit references to that animal. Yet a student fine-tuned on the data could subsequently show an increased preference for the same animal.
The phenomenon is important because conventional data inspection may not reveal what information is actually being transmitted through a training dataset.
The new Stanford research approaches the problem from a different direction: instead of simply asking whether hidden information exists, it attempts to recover a readable description of that information.
How SALVE Detects Hidden AI Behaviors?
SALVE uses a two-stage process.
First, the researchers optimize a soft prompt against the dataset while keeping the underlying language model frozen. The soft prompt consists of continuous embedding vectors rather than ordinary words. Its objective is to make the model reproduce the behavior represented in the dataset as closely as possible.
The resulting representation is not directly readable. SALVE therefore performs a second stage in which the model is asked to verbalize the optimized representation.
Simply asking the model to describe the soft prompt can produce unreliable results. The researchers address this with sentence-level beam search, evaluating candidate pieces of text according to how well they continue to explain the dataset. This combines continuous optimization with a search over readable language.
The approach is significant because it connects two otherwise difficult objectives: finding a representation that fits the training data and expressing that representation in language that humans can inspect.
SALVE Recovered Hidden Animal Preferences
The researchers first evaluated SALVE using a controlled subliminal-learning setup.
Their teacher model was Qwen2.5-7B-Instruct, which received a system instruction to prefer one of four animals: cats, dogs, eagles or owls. The model was then given unrelated number-sequence tasks, producing datasets that did not explicitly mention the preferred animal. The study used 10,000 examples per dataset after filtering malformed outputs.
SALVE recovered prompts explicitly naming the correct animal in 18 of 20 experimental runs across the four animal preferences and five random seeds.
The recovered prompts were not necessarily identical to the original hidden instruction. Instead, they were semantically similar descriptions of the underlying preference. When used as system prompts, the recovered instructions generated the expected animal preference at a reported frequency of 0.88.
The comparison also matters. Several other optimization approaches could reduce dataset loss without producing an interpretable description of the hidden behavior. The researchers report that the other tested methods did not identify the correct animal in the 20 main runs.
Dataset Can Contain Information Even When the Student Does Not Learn It
One of the more notable findings is that the presence of hidden information in a dataset and the ability of a particular student model to learn that information are not necessarily the same thing.
SALVE was able to recover the teacher’s animal preference from some datasets even when standard student fine-tuning produced little observable change in the student’s behavior.
The experiments included Llama 3.1 and Llama 3.2 models where conventional subliminal learning was limited, yet SALVE could still identify prompts naming the relevant animal.
This distinction could matter for AI dataset auditing. A dataset might contain a behavioral signal even if one particular training configuration fails to extract it.
SALVE Was Tested Beyond Animal Preferences
The researchers also examined whether the method could detect hidden signals in settings beyond the original prompted-teacher experiment.
SALVE was tested on mixtures of subliminal data and unrelated numerical data, data generated by activation-steered teachers, and preference datasets selected using Logit-Linear Selection. The study also examined behavioral properties including sycophancy and misalignment.
Results varied by setting.
For activation-steered teachers, for example, SALVE recovered animal-related prompts less reliably than it did for explicit system prompts. Across 108 runs, the method produced an animal-naming prompt in 22 cases, while another 36 runs considered an animal-naming candidate during search but ultimately selected another prompt.
The researchers also report evidence that SALVE could detect sycophancy and misalignment-related signals in selected preference datasets. These experiments extend the method beyond the simpler animal-preference demonstration, although they do not establish that SALVE can reliably audit arbitrary real-world datasets.
What SALVE Could Mean for AI Training Data Audits?
The potential application is dataset auditing.
Traditional dataset filtering can look for explicit terms, topics or unwanted examples. Subliminal learning presents a different problem because information may be encoded in model-specific patterns that are not obvious from the visible content.
SALVE provides a possible complementary approach: search for a latent representation that explains the dataset and then translate that representation into language that an evaluator can inspect. The researchers describe the method as a way to proactively detect subliminal learning effects before the data is used to train another model.
That does not make SALVE a complete safety scanner. The current work is primarily experimental, and its ability to verbalize hidden information depends partly on the model’s ability to translate continuous representations into language.
SALVE Has Important Limitations
The study does not demonstrate that every hidden behavior can be recovered from arbitrary training data.
The researchers note that a natural-language prompt may be incomplete or confabulated, while some information encoded in a dataset may not be expressible as a single natural-language instruction. The experiments also rely heavily on constructed datasets and a relatively limited set of behaviors and open-weight model families.
The activation-steering experiments further show that recovery can become substantially less reliable when the hidden behavior does not correspond neatly to an explicit natural-language instruction.
As a result, SALVE is better understood as an experimental interpretability and dataset-auditing technique rather than a general-purpose detector for hidden AI behavior.
The research nonetheless adds another tool to the study of subliminal learning. Earlier work established that apparently unrelated data can carry behavioral traits from a teacher model; SALVE focuses on making those hidden signals more interpretable.
For AI developers, that distinction could be important: inspecting what a dataset visibly says may not always reveal everything a model can learn from it, and SALVE explores one way of making some of those hidden signals easier to investigate.
Also Read –
SIFT Makes Self-Improving Coding Agents More Efficient
ScientistTwo Automates Autonomous AI Research
Source
arXiv — Verbalizing Subliminal Learning Effects Using Text Optimization
alphaXiv — Verbalizing Subliminal Learning Effects Using Text Optimization
Subliminal Learning – Language models transmit behavioral traits via hidden signals in data
Hugging Face – Subliminal Learning paper
Stanford – Christopher Potts research papers