
A new paper from researchers at Meta Superintelligence Labs proposes a different way to scale AI agents: instead of simply giving an agent more computation, use a dedicated controller to decide how that computation should be spent.
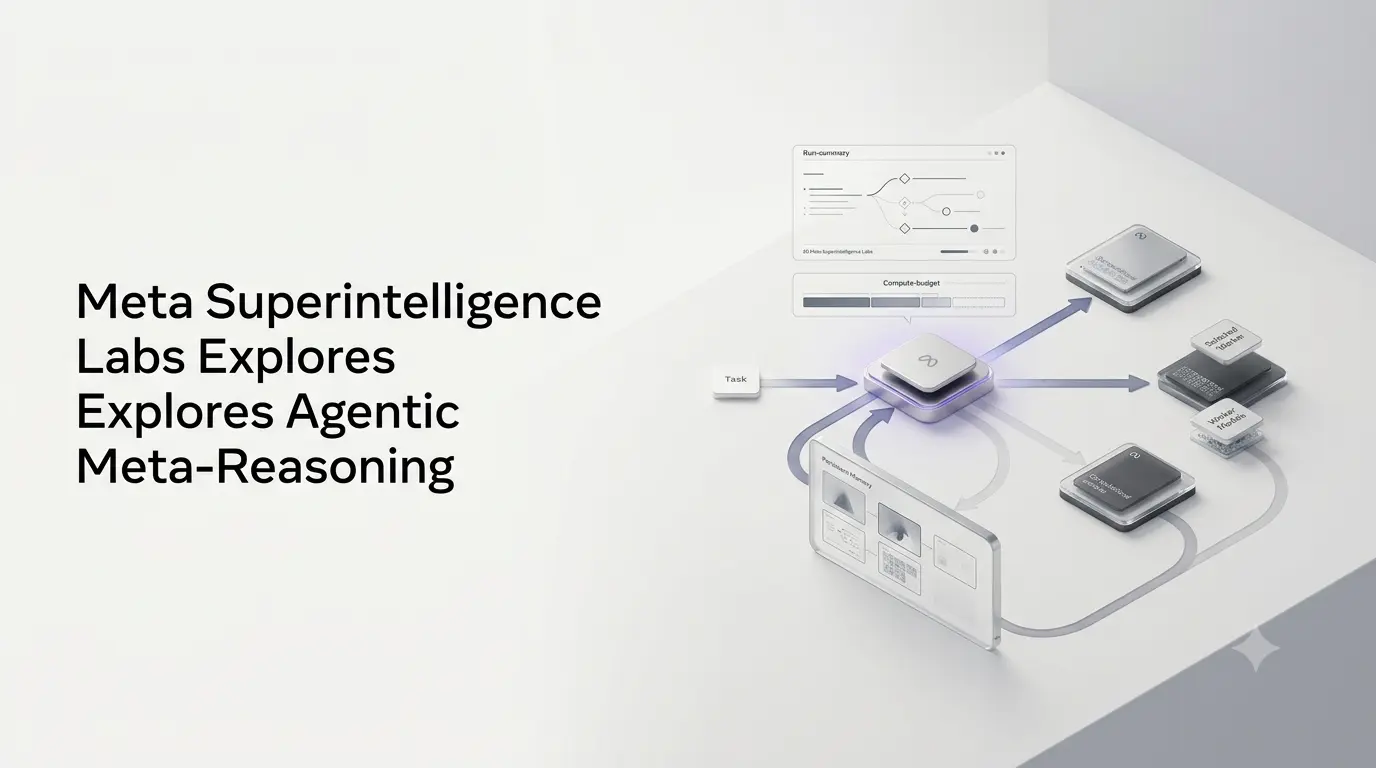
The approach, called agentic meta-reasoning, separates task execution from control. Worker models perform the actual work, while a controller tracks progress, considers possible next actions, evaluates them against the remaining compute budget and dispatches the selected work.
On ProgramBench, the researchers report a 71.5% mean test-pass rate with GPT-5.5, compared with 63.7% for a matched Direct Control Agent using the same workers and compute budget. The paper also reports gains of 3.6 to 4.2 percentage points across three other reasoning benchmarks.
Quick Summary
- Meta Superintelligence Labs published a paper introducing agentic meta-reasoning for longer AI agent runs.
- The approach separates task execution from control, using a dedicated controller to decide what computation should happen next.
- The controller maintains a compact summary while full worker outputs remain in persistent memory.
- On ProgramBench, the paper reports 71.5% for GPT-5.5 with meta-reasoning versus 63.7% for matched direct control at the cited budget.
- Across other benchmarks, the paper reports 3.6–4.2 percentage-point gains over direct control averaged across three frontier models.
- The paper also notes an important limitation: controller overhead can hurt performance when the available compute budget is small.
What Is Agentic Meta-Reasoning?
The paper addresses a problem that becomes more important as AI agents run for longer periods: deciding what to do next can become nearly as important as executing an individual task.
A conventional agent can accumulate an increasingly large history of previous actions, observations and outputs. The system then uses that history to determine its next step.
The proposed architecture separates those responsibilities.
Workers perform task-level computation, while a controller manages the overall execution strategy. The controller can decide whether to continue an existing line of work, explore another option, reuse an earlier result or stop.
This creates what the researchers describe as an explicit control process around the underlying task-solving models.
How the Meta-Reasoning Controller Works?
The controller operates through a recurring four-stage process.
- Update the state: Maintain a compact summary of what has been established.
- Propose work: Consider possible next computations or actions.
- Evaluate options: Estimate the value of each option given the remaining budget.
- Dispatch work: Send the selected task to a worker together with relevant earlier outputs.
The design also uses persistent memory.
Instead of repeatedly passing the complete history to the controller, worker outputs remain available in memory and can be retrieved when necessary. The controller therefore works with a compact representation of the run rather than an ever-growing transcript.
According to the paper, controller calls count against the same compute budget as worker calls.
Meta-Reasoning Improves GPT-5.5’s ProgramBench Result
ProgramBench is one of the paper’s central evaluations. It tests long-horizon coding ability through program reconstruction tasks.
The researchers compared their meta-reasoning setup with both a matched Direct Control Agent and existing production coding agents.
| System | ProgramBench result |
|---|---|
| GPT-5.5 + Meta-Reasoning | 71.5% |
| GPT-5.5 + Direct Control | 63.7% |
| Codex | 58.0% |
| Opus 4.8 + Meta-Reasoning | 67.2% |
| Claude Code | 65.5% |
The most important controlled comparison is 71.5% versus 63.7%. Both configurations use the same underlying workers and compute-budget allowance; the primary difference is the control strategy.
The 58.0% Codex result is a separate comparison against a production coding agent, so it should not be interpreted as a direct apples-to-apples comparison with the 63.7% Direct Control baseline.
Gains Extend Beyond Coding
The researchers also evaluated the approach on three other benchmarks covering different forms of reasoning:
- IMO ProofBench-Advanced
- ARC-AGI-2
- LongCoT-mini
Across these benchmarks, the paper reports improvements of 3.6 to 4.2 percentage points over Direct Control, averaged across Gemini 3.1 Pro, GPT-5.5 and Opus 4.8.
The researchers report higher point estimates in all 12 matched model-and-benchmark comparisons at the main tested budgets.
These results suggest that the control mechanism is not limited to software engineering tasks.
Why Separating Control From Task Execution Matters
Long-running AI agents have to make many decisions beyond generating the next answer.
An agent might need to determine whether to:
- Continue investigating an existing hypothesis
- Ask another worker to critique a result
- Start a different approach
- Reuse an earlier artifact
- Spend additional computation verifying an answer
- Stop and submit the current result
A system that treats these decisions as an explicit reasoning problem can potentially allocate its inference budget more deliberately.
This is particularly relevant as AI assistants evolve into AI agents capable of completing multi-step research, coding, analysis and automation tasks.
The Approach Scales Differently With More Compute
One of the paper’s notable findings concerns larger inference budgets.
The researchers report that meta-reasoning continues to improve across the tested budget ranges in cases where Direct Control begins to plateau.
This distinction matters because simply increasing the number of model calls does not guarantee better results. An agent needs a mechanism for deciding which additional computation is worth performing.
The paper therefore frames structured control as another potential scaling dimension alongside model capability and inference-time compute.
The System Has Important Limitations
The proposed approach does not improve performance in every operating condition.
The researchers report that controller overhead can hurt results at small budgets. Some of the available computation must be spent on deciding what work to perform rather than directly performing the task.
The paper also notes that its experiments evaluate the complete meta-reasoning design rather than isolating the contribution of every individual component.
That means the results demonstrate the value of the overall architecture, but they do not establish that every part of the controller contributes equally.
What This Means for AI Agents?
The research points toward a broader architectural shift in how developers may think about agentic systems.
Today’s AI agents often focus heavily on improving the underlying large language model, adding tools or expanding context windows. The new work suggests another possibility: improving the control layer that determines how an agent uses its available computation.
For complex workloads, this could influence systems designed for:
- Long-running coding tasks
- Autonomous research
- Mathematical reasoning
- Software debugging
- Multi-step analysis
- AI-assisted planning
- Agentic automation
Rather than treating an agent as one model repeatedly calling tools, developers can instead view it as a system containing separate execution, memory and control components.
Why the Paper Matters for Agentic AI?
The significance of the research is less about a single benchmark score and more about the problem it isolates.
As AI agents become capable of longer runs, managing the execution process becomes increasingly difficult. More context, more workers and more inference compute can introduce additional opportunities for wasted computation or poor decisions.
Agentic meta-reasoning provides one research direction for addressing that problem by making control itself an explicit inference-time process.
The approach also fits into a broader movement toward test-time scaling, where additional computation is used during inference rather than relying exclusively on larger pretrained models.
Also Read –
Just-in-Time Memory: A New Approach to AI Agent Memory
Souce
Thinking Before Thinking: Scaling Agentic Inference Through Meta-Reasoning
DAIR.AI Academy – Paper overview and key findings
arXiv HTML — Full research paper